OKLM
loadtokenizequantize
runtrainserveagent
01
GGUF
safetensors
HF dirs
safetensors
HF dirs
02
convert
quantize
imatrix
quantize
imatrix
03
BPE
SentencePiece
train-tokenizer
SentencePiece
train-tokenizer
04
run / chat
describe
transcribe, speak
describe
transcribe, speak
05
train / LoRA
chat-data
rl
chat-data
rl
06
serve
dashboard
oklm-gui
dashboard
oklm-gui
07
agent
tools, skills
MCP
tools, skills
MCP
LLM
Token
Logits
Forward / backward
GGUF / safetensors
imatrix
LoRA
SFT / RL
Backend
MCP
>
tokens>
>
logits>
>
TRANSFORMER
AGENT
ggmlllama.cppBLAS
sentencepiecetiktokenHF tokenizers
ONNXPyTorch
GGUF v3safetensorsggml block quants
byte-level BPESentencePiece-BPEJinja
OpenAI API
01
M0-M1
M2-M3
M4
OpenCL
M5
M6
M7-M8
M9
v0.1.0
M10-M16
M17
RAG
1.0.0
| llama-quantize, gguf-py | ||
| Hugging Face tokenizers | ||
| jinja2 | ||
| llama.cpp | ||
| llm.c + PyTorch | ||
| llama.cpp mtmd | ||
| llama.cpp | ||
| llama.cpp | ||
02
F32 F16 BF16
Q4_0 Q4_1 Q5_0 Q5_1 Q8_0
Q2_K .. Q6_K Q8_K
IQ4_NL IQ4_XS
MXFP4 NVFP4
TQ1_0 TQ2_0 Q1_0 Q2_0
PQ2_0 PTQ1_0
IQ1_S .. IQ3_S
$ oklm convert qwen3-8b-hf/ \
--out q.gguf --type bf16
$ oklm imatrix -m q.gguf -f calib.txt \
-o q.imatrix.gguf
$ oklm quantize --imatrix q.imatrix.gguf \
q.gguf q4.gguf Q4_K_M
$ oklm info q4.gguf
format : GGUF v3, alignment 32
general.architecture = "qwen3"
qwen3.block_count = 36
# same bytes as llama-quantize's file
LlamaMistral / Mistral 3Qwen2 / 3 / 3.5
Gemma 1 .. 4Phi-2 / Phi-3GPT-2 / StarCoder2
DeepSeek-CoderLFM2gpt-ossGLM-4
GLM-4.5 .. 4.7-FlashOLMoEGranite MoEDeepSeek V2 / V3Qwen3.6 MoELFM2 MoE
SmolVLMLLaVA 1.5 / 1.6Qwen2-VL / 2.5-VLUltravoxWhisperOuteTTS / Soprano
CPU
oklm tune -m model.gguf
VULKAN
--backend vulkan
OPENCL
--backend opencl
ROCM
train --backend rocm
$ oklm plan -m big-moe.gguf -c 8192
# fits / fits with N layers on the GPU /
# only with the expert cache
$ oklm plan --list --recommend
# every GGUF under models/ and its verdict
$ oklm run -m big-moe.gguf --n-cpu-moe all \
--expert-gpu auto -p "Hi"
$ oklm tune -m moe.gguf --expert-cache 4
10.4
6.3
7.4
17.1
33.9
9.9
5.5
6.9
| pp 1 th | pp 4 | pp 16 | tg 1 th | tg 4 | tg 16 | |
|---|---|---|---|---|---|---|
| SmolLM2-135M Q4_K_M | 1.29 | 1.35 | 1.52 | 1.56 | 1.09 | 1.16 |
| Llama-3.2-1B Q4_K_M | 1.08 | 1.09 | 1.20 | 1.16 | 1.00 | 1.09 |
| Qwen3-8B Q8_0 | 1.76 | 1.76 | 1.80 | 1.22 | 1.00 | 1.08 |
| OLMoE-1B-7B Q4_K_M | 1.78 | 1.75 | 1.94 | 1.17 | 0.99 | 1.00 |
| GLM-4.7-Flash Q4_K_M | 1.29 | 1.33 | 1.42 | 1.16 | 1.02 | 0.98 |
| pp512 | tg128 | |
|---|---|---|
| SmolLM2-135M Q8_0 | 1.37 | 1.17 |
| SmolLM2-135M Q4_K_M | 1.15 | 1.04 |
| Llama-3.2-1B Q4_K_M | 0.84 | 0.95 |
| Qwen3-8B Q4_K_M | 0.86 | 0.90 |
| Qwen3-8B Q8_0 | 1.65 | 0.92 |
| Granite-3.1-1B-A400M | 1.06 | 1.09 |
| OLMoE-1B-7B | 0.85 | 0.88 |
| GLM-4.7-Flash | 1.04 | 0.89 |
| prompt | ||
|---|---|---|
| RX 7900 XT, Llama-3.2-1B, Vulkan | 16 235 | 509 |
| RX 7900 XT, Llama-3.2-1B, OpenCL | 14 861 | 403 |
| RX 7900 XT, Qwen3-8B, Vulkan | 2 663 | 112 |
| RX 7900 XT, Qwen3-8B, OpenCL | 2 747 | 94.6 |
| UHD 750, Llama-3.2-1B, Vulkan | 55 | 22.1 |
| UHD 750, Llama-3.2-1B, OpenCL | 8.9 | 5.4 |
03
01 CLI
oklm run | chat | ppl
02 API
oklm serve -m model.gguf
03 GUI
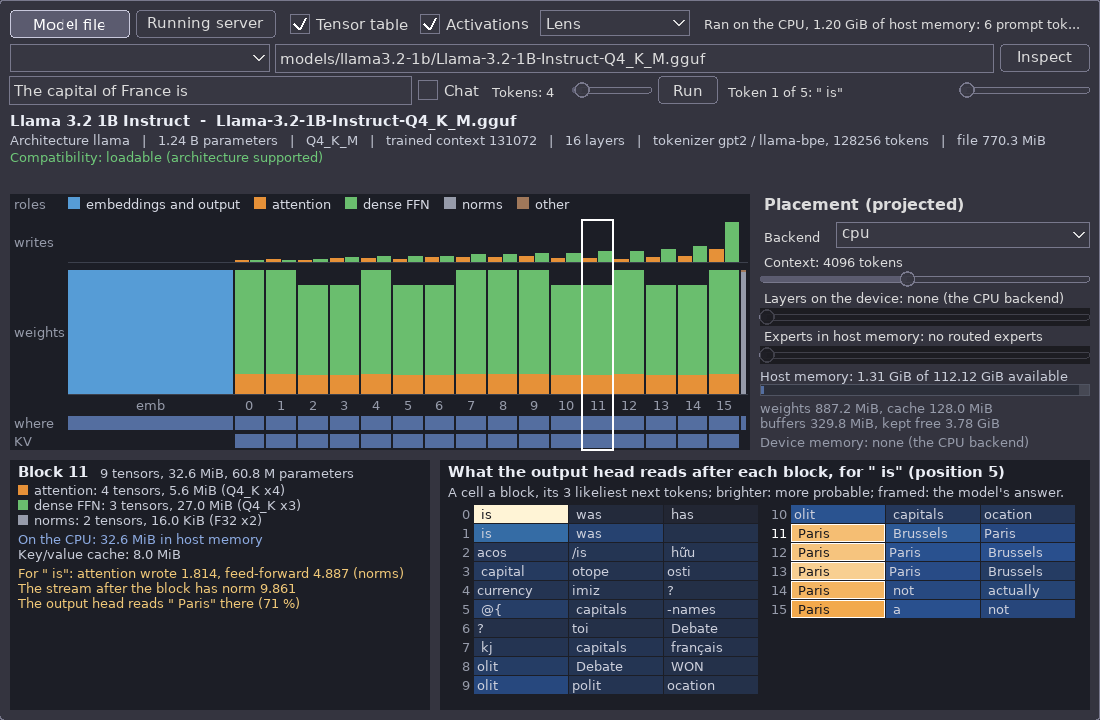
oklm-gui --tool NAME
04 MULTIMODAL
oklm describe | transcribe | speak | rag
05 AGENT
oklm agent -m qwen3-8b.gguf
06 TRAINING
oklm train | rl
versionhelpdevicestypesinfoplanmodelstune
convertquantizeimatrixsplitmergelora-mergeexpert-pack
tokenizetrain-tokenizerrunchatppl
ingestembedrerankragdescribetranscribespeak
serveagentpermissionsaudit
trainrlabliteraterefusals
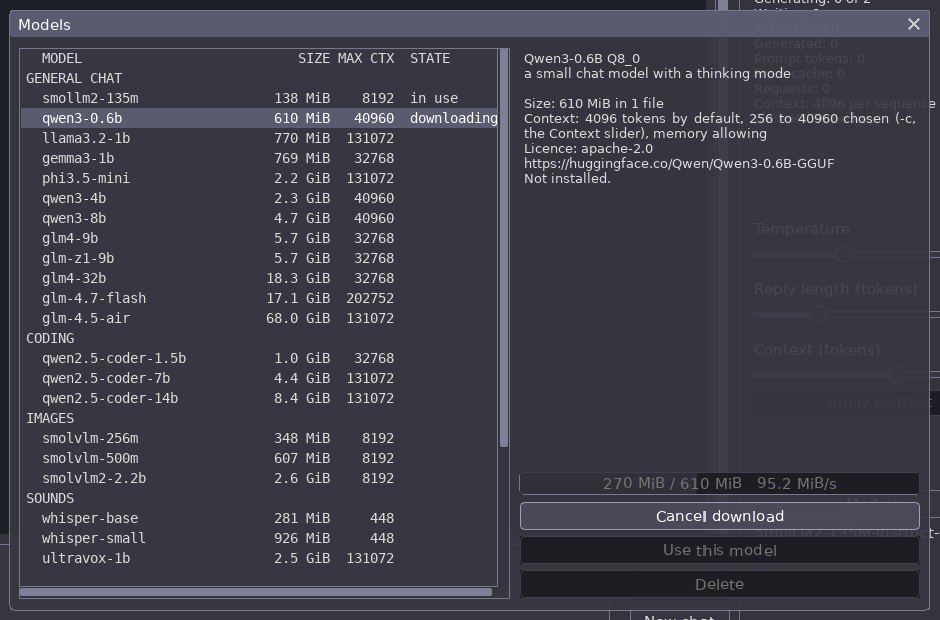
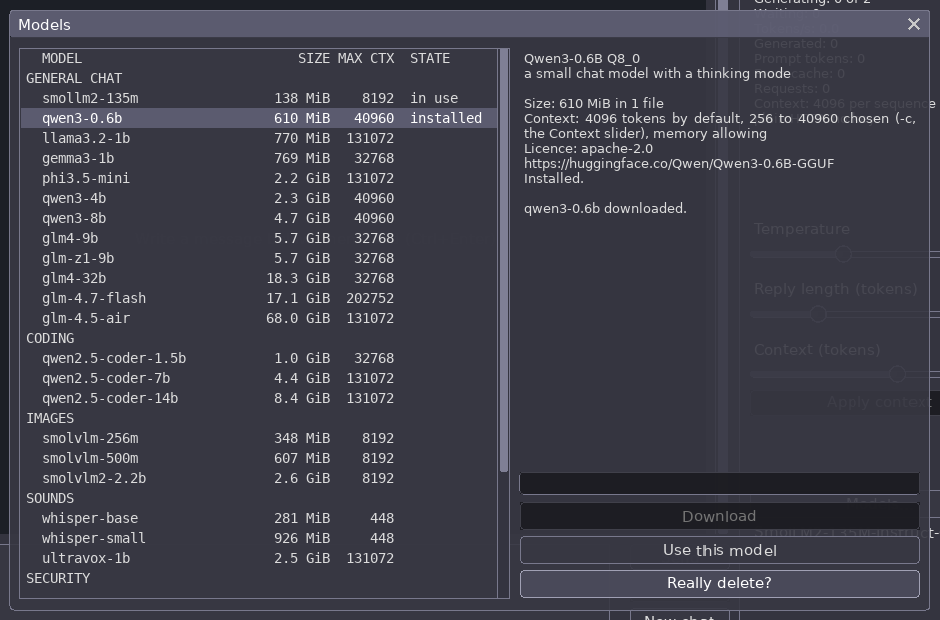
$ oklm models
General chat
qwen3-8b 4.7 GiB
glm-4.7-flash 17.1 GiB
Coding
qwen2.5-coder-7b 4.4 GiB
Security
foundation-sec-8b 4.6 GiB ...
$ oklm models pull qwen3-8b
Qwen3-8B-Q4_K_M.gguf 41.2 % 98.6 MiB/s
$ oklm chat -m qwen3-8b
$ oklm run -m qwen2.5-0.5b-instruct-q4_k_m.gguf \
-p "The capital of France is" -n 24 --temp 0
The capital of France is Paris. It is the
largest city in Europe and ...
prompt: 5 tokens (976.6 t/s); generation:
24 tokens in 0.071 s (336.8 t/s)
$ oklm chat -m qwen3-4b.gguf --tools tools.json
$ oklm run -m model.gguf --json-schema person.json
$ oklm ppl -m model.gguf -f tinyshakespeare.txt
266
581
4 979
6 388
7 265
1.85 s
0.026 s
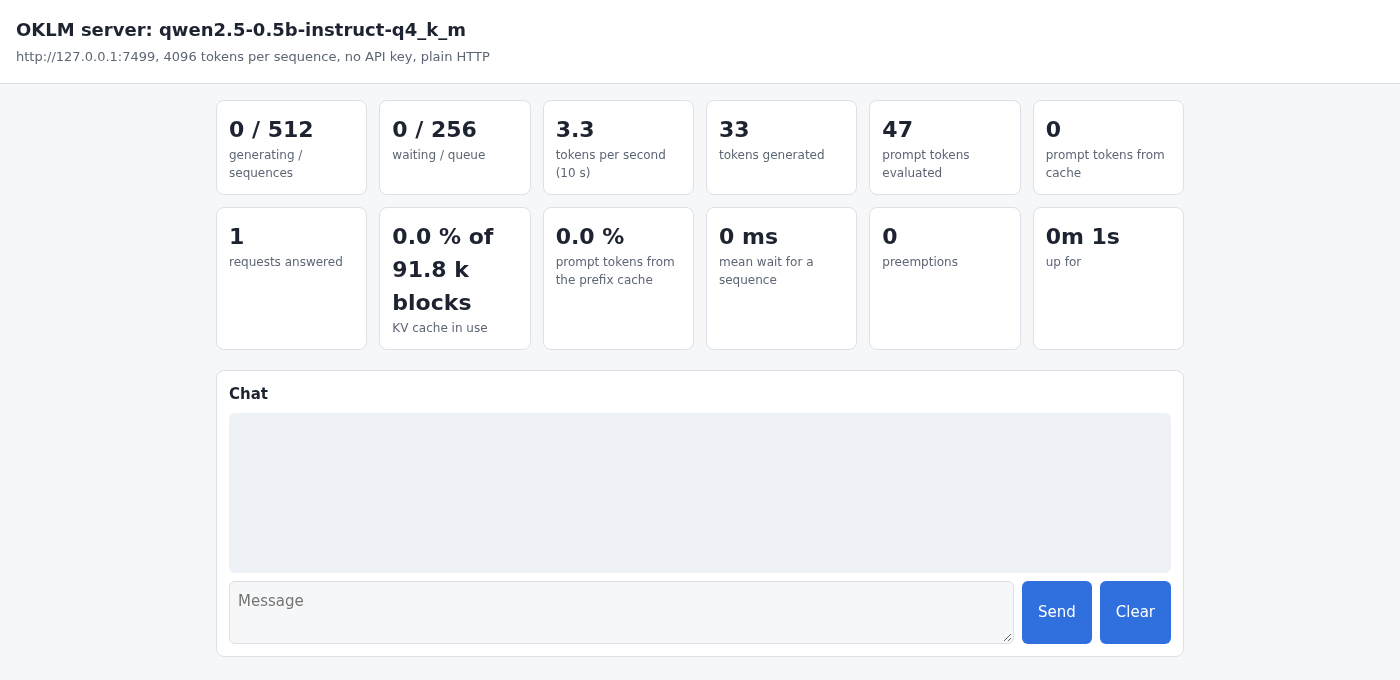
$ oklm serve -m model.gguf \
--prefix-dir cache/prefix --spec-grammar
# Qwen2.5-0.5B Q4_K_M, CPU: 26 MB on disk
Ultravox
Whisper
TXT, MD, CSV, JSON, HTML, DOCX, PDF
$ oklm describe -m SmolVLM-256M-Instruct-Q8_0.gguf --mmproj mmproj-SmolVLM-256M-f16.gguf -p "What is this?" photo.jpg
$ oklm describe -m ultravox.gguf --mmproj mmproj-ultravox.gguf -p "Who speaks?" clip.ogv --frames 8
$ oklm transcribe -m whisper-large-v3-turbo --backend vulkan talk.ogg
$ oklm run -m model.gguf --doc report.docx -p "Summarize this report."
| OuteTTS 0.2, CPU | 6.6 s | 0.51 |
| OuteTTS 0.2, OpenCL | 0.9 s | 3.7 |
| OuteTTS 0.2, Vulkan | 0.7 s | 4.8 |
| Soprano 1.1, CPU | 0.2 s | 12.6 - 13.1 |
| Soprano 1.1, OpenCL | 0.06 s | 39 |
| Soprano 1.1, Vulkan | 0.06 s | 44 - 47 |
$ oklm speak -m soprano-1.1-80m -o speech.wav "Hello world."
$ oklm serve -m model.gguf --transcribe-model whisper-base \
--speak-model outetts-0.2-500m
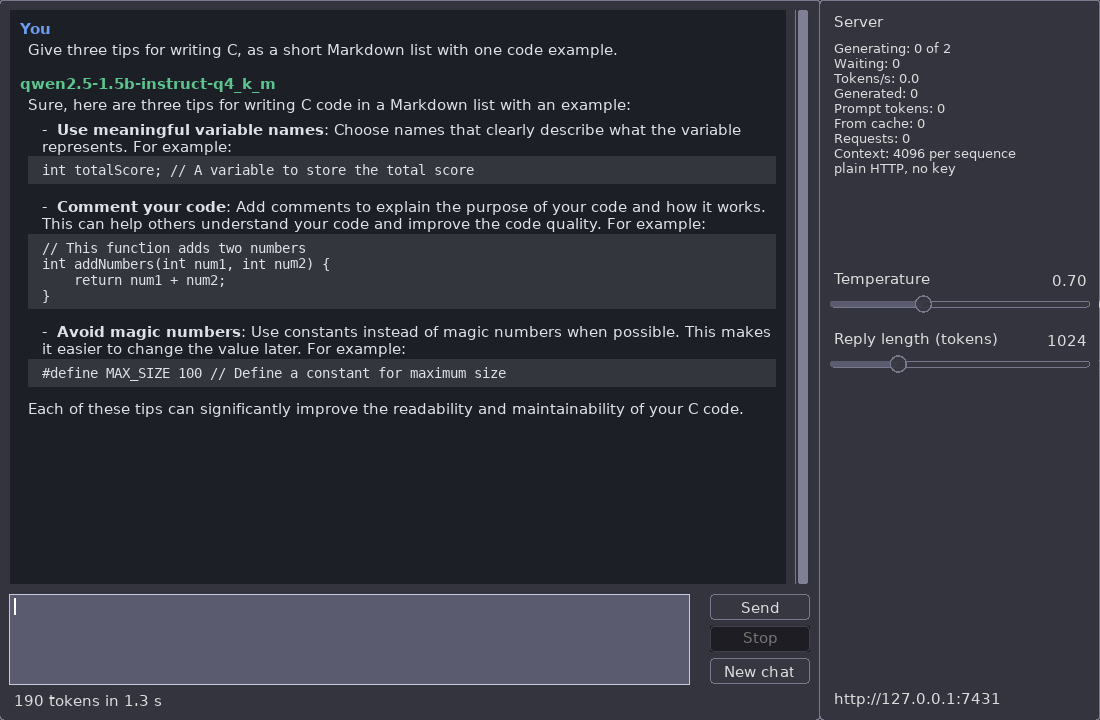
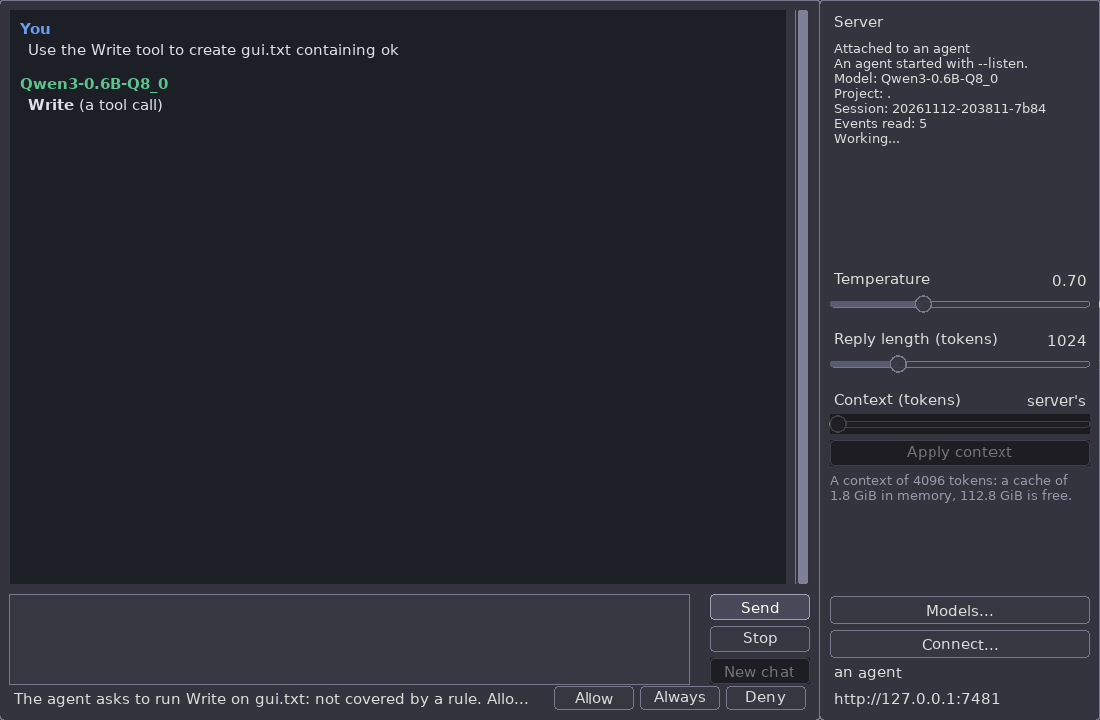
$ oklm-gui -m qwen3-8b --talk
| SciFact | docs OKLM | |
|---|---|---|
| 71.27 | 60.48 | |
| BM25 | 67.41 | 64.53 |
| 71.29 | 69.78 | |
| 73.04 | 70.61 |
$ oklm rag index docs --out docs.gguf -m bge-small.gguf
$ oklm rag search docs.gguf "KV cache precision" -k 5
$ oklm run -m qwen3-8b.gguf --rag docs.gguf -p "..."
$ oklm embed -m bge-small.gguf "one vector a text"
$ oklm rerank -m ms-marco-MiniLM-L-6-v2 -q "..." "p1" "p2"
$ oklm agent -m Qwen3-8B-Q4_K_M.gguf
default model: Qwen3-8B, 32768-token context
> fix the failing test in tests/io
Read tests/io/test_gguf.c
Grep "oklm_gguf_open" src/
Edit src/io/gguf.c [diff shown, ask]
Bash make test [allowed by rule]
$ oklm agent --url http://host:7430 --remote-model x
$ oklm agent -m MODEL -p "fix the build" \
--output-format stream-json
$ oklm agent --worktree feature-x
default
acceptEdits
plan
bypass
HOOKS
MCP + PLUGINS
GIT
04
train -f text.txt --arch llama
FINE-TUNE
train -m model.gguf -f text.txt
RESUME
train --resume ckpt-000600.gguf
LORA / QLORA
train -m m.gguf --lora 8 --quantized-base
SFT
train --chat-data conv.jsonl
RL
rl -m model.gguf -f tasks.jsonl
17x
4.3 GB
344 ms
2.4 M
# checkpoint = model GGUF + optimizer sidecar
build/nano/nano-001200.gguf
build/nano/nano-001200.gguf.train
| F32 | 3.1329 |
| 3.2365 | |
| 3.1347 |
| llm.c | 4.10778 |
| OKLM | 4.10773 |
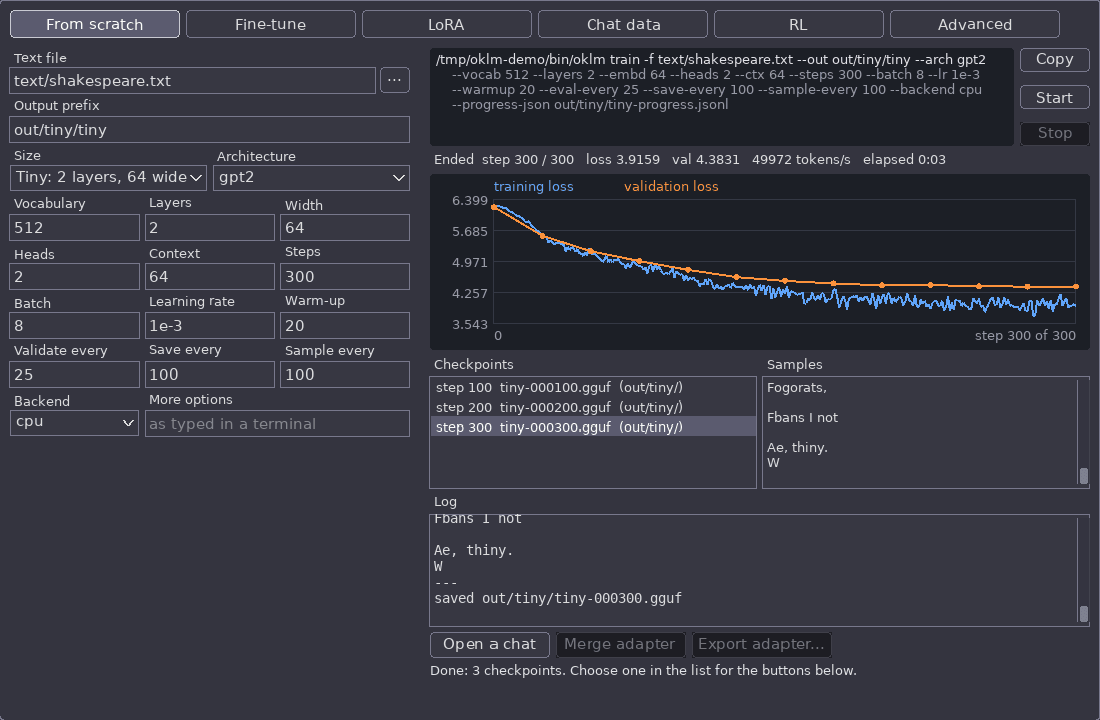
$ oklm train -f tinyshakespeare.txt \
--out build/nano/nano --vocab 2048 \
--layers 6 --embd 256 --heads 8 --ctx 256 \
--steps 1200 --lr 1e-3 --warmup 100
$ oklm run -m build/nano/nano-001200.gguf \
-p "ROMEO:" -n 80 --temp 0.8
ROMEO:
O, with his grave, and with a din
Must, as I have a painted to do.
ROMEO:
O, nurse; for I pray you; if you shall
| OKLM-Nano | 5.3 M | Tiny Shakespeare | - | 18 min (CPU) | 3.99 |
| OKLM-Micro | 33.6 M | SmolTalk | 1 h + 35 min | 1.39 / 2.93 | |
| OKLM-Small | 88.1 M | SmolTalk | 6.7 h + 35 min | 3.51 / 2.37 |
3.83 > 3.30
34.96 > 27.40
10 MB
210
| backend | LoRA all | LoRA qkvo | |
|---|---|---|---|
| opencl | 156 ms | 140 ms | 119 ms |
| rocm | 110 ms | 102 ms | 91 ms |
| cpu | - | 3.3 s | - |
$ oklm train -m SmolLM2-135M-f16.gguf -f shakespeare.txt \
--out build/lora/smol --lora 8 --lora-alpha 16 \
--lora-targets all --steps 200 --backend rocm
$ oklm run -m SmolLM2-135M-f16.gguf \
--lora build/lora/smol-000200.gguf -p "ROMEO:"
IMATRIX + QUANTIZE
oklm imatrix ; oklm quantize --imatrix
LORA-MERGE / SPLIT / MERGE
oklm lora-merge base.gguf ad.gguf out.gguf
ABLITERATE + REFUSALS
oklm abliterate ; oklm refusals --ref
PPL + TUNE + INFO
oklm ppl ; oklm info -t ; oklm tune
0
0
0
0
0
0
0
0
| Qwen3-8B | |
| Qwen3-4B | |
| Qwen3-0.6B |
OKLM
C170 depbit-exact
CPUVulkanOpenCL